Related Topics:
Backbone Next Data Center Interconnect 800G Transceiver Liquid Cooling-
Fiber optic cables can also be connected to the back of the router
The fiber optic cable does not plug directly into a standard home router because the signal type must be translated. The fiber line terminates at the Optical Network Terminal (ONT), which is typically supplied and installed by the internet service provider. This comprehensive guide combines industry standards with field-tested practices to ensure you achieve a rock-solid. To connect your fiber optic cable to a router, ensure you have the following: Fiber optic modem (ONT): Most fiber connections require an Optical Network Terminal (ONT), provided by your ISP. Here's a simple guide to help you through the process: 1.
[PDF Version]
-
How to set up an AI Xiaozhi server
This document provides instructions for deploying the xiaozhi-server platform. For setting up a local development. If the network configuration page does not automatically redirect, you need to manually open the browser and visit 4G is supported, the maximum compatibility option should be turned on for iPhone hotspot). The SSID. XiaoZhi AI is an open-source intelligent voice robot based on ESP32-S3 development, integrating wake word detection, AI conversation, device control, and multi-protocol communication capabilities. Through this project, we aim to help more people get started with AI hardware development and understand how to integrate rapidly evolving large language models into actual. This project applies the Media Kit to implement an AI voice assistant, which requires a certain level of programming proficiency as well as familiarity with ESP-IDF and open-source large models.
[PDF Version]
-
First AI Server in Northern Europe
We're launching Stargate Norway—OpenAI's first AI data center initiative in Europe under our OpenAI for Countries program. (“Nscale”), Aker ASA (“Aker”) and OpenAI today announced the launch of. In a landmark move for European AI infrastructure, Nscale Global Holdings, Aker ASA, and OpenAI have unveiled Stargate Norway: a major new gigafactory project in Narvik, Northern Norway. The companies plan is to invest 10 billion Norwegian kroner in the first phase of the project, called “Stargate Norway. The site aims to deliver 100,000 NVIDIA graphics processing units (GPU) by the end of 2026.
[PDF Version]
-
AI decoding server
This document shows how to use Speculative Decoding with vLLM to reduce inter-token latency under medium-to-low QPS (query per second), memory-bound workloads. The pace of generative AI (gen AI) innovation demands powerful, flexible and efficient solutions for deploying large language models (LLMs). Today, we're introducing Red Hat AI Inference Server. To train your own draft models for optimized speculative decoding, see vllm-project/speculators for seamless training and integration with. This tutorial shows how to build and serve speculative decoding models in Triton Inference Server with vLLM Backend on a single node with one GPU. This reduces the number of infer requests to the main model, increasing performance. Type $help for helpful information! The second best way is to use cargo install ciphey and call it with ciphey. You can also git clone this repo and run docker build. Weave CLI unifies 11 vector databases into one workflow.
[PDF Version]
-
How to add AI to the server interface
By setting up your local AI server today, you're preparing for an AI future where control, privacy, and customization are in your hands. Instead of depending on cloud APIs, you can bring the intelligence directly onto your own hardware, which unlocks: Improved privacy and security: With locally hosted AI, your data never. In my case, I set up a new, separate system with one purpose, as an AI server. The. To begin with, this comprehensive guide dives into a concept inspired by the principles of the Model Context Protocol (MCP). Nevertheless, we showcase a custom AI server built using JavaScript, deployed on AKS, and seamlessly integrated with Azure OpenAI. Running LLM locally offers several advantages, especially for users concerned with. In this guide, you will learn how to run advanced models such as Llama 3, Mistral, Phi-3, and Gemma locally on Windows and connect them with SQL Server through MCP to get smart, natural-language insights while keeping all your data completely private. Let me be direct about something: I'm not neutral on this topic.
[PDF Version]
-
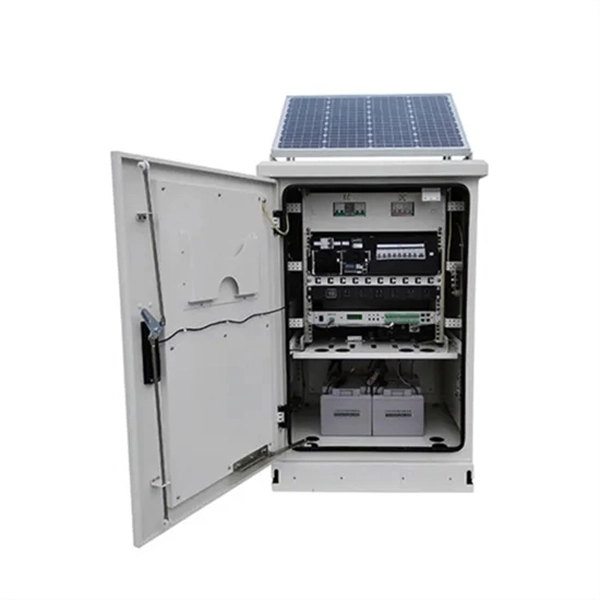
Liquid-cooled charging piles AI server power supplies Huawei data center
This article discusses the necessity and benefits of liquid cooling in AI data centers, focusing on the challenges posed by high-power AI servers and the advantages of Vertical Power Module (VPM) systems. AI applications, high-performance computing, and GPU servers have driven the power consumption of a data center rack as high as 20 kW, 30 kW, or even 50 kW. To address this challenge, Huawei. AI factories are pushing data center power and cooling requirements beyond traditional limits, making integrated AI data center infrastructure essential. Why space limitations, power-delivery constraints, cooling inefficiencies, and sustainability pressures present challenges for scaling legacy data centers. How. NJFX and Bala Consulting Engineers are collaborating to develop a data hall, internally named Project Cool Water, which represents the first purpose-built cable landing station campus in North America to support “liquid-to-the-chip” AI-ready infrastructure. Over the past three years, we've tracked.
[PDF Version]